
Bioassay — Slope Ratio Method
Bioassay — Slope Ratio Method compares one or more test preparations with a standard when the response is linear in dose itself and all preparations share a zero-dose response, as in vitamin or growth assays. It checks regression, common intercept and linearity, then reports relative potency with a confidence interval, a Pass/Fail check against limits, diagnostics and a dose-response plot. Bioassay — Slope Ratio Method is one of the bioassay tools in Zometric Statistical Software, run from the Statistical Workspace or its own tool page.
Last reviewed
Key takeaway
The slope ratio method estimates the relative potency of test preparations by fitting straight lines of response against dose (not log dose) with a common intercept; potency is the ratio of each test slope to the standard slope.
On this page
What is Bioassay — Slope Ratio Method?
A slope ratio assay estimates the relative potency of one or more test preparations against a standard preparation. It is used in biological assays such as vitamin, growth-factor and growth-promotion assays. It works on the dose scale itself, not on log dose. This is the difference from the Bioassay — Parallel Line Method.
The model is a straight line of response on dose for each preparation. All preparations share one intercept, the response expected at zero dose (the blank). Each preparation has its own slope. The relative potency of a test preparation is the ratio of its slope to the slope of the standard:
R = b(test) / b(standard)
The tool fits the common-intercept model by least squares. It gives the confidence interval for R with Fieller's theorem, and it reports Fieller's g. When g is below 1 the interval is reliable. The design and the validity checks follow the general approach of the statistical analysis of biological assays in the European Pharmacopoeia (chapter 5.3) and the United States Pharmacopeia (general chapter on the design and analysis of biological assays).
Three validity checks must pass before you report a potency:
- Regression: the dose-response relationship is statistically significant.
- Intercept: the preparations agree on the blank response, so a common intercept is acceptable.
- Linearity: the response is linear in dose over the range tested.
Slopes that differ between preparations are expected, because that is how potency differences are measured. This is not a validity failure.
When to use it
Use it when:
- You compare one or more test preparations with a standard, and the response is expected to increase linearly with dose itself.
- Each preparation is tested at several dose levels, and a shared zero-dose (blank) treatment is included.
- You need a potency estimate with a confidence interval and a Pass/Fail check against acceptance limits.
When not to use it, and what to use instead:
- The response is linear in the logarithm of dose: use Bioassay — Parallel Line Method.
- The response is a count of subjects that responded, out of a number tested: use Bioassay — Quantal Response Method.
- The dose-response curve is S-shaped, with upper and lower plateaus: use Bioassay — Four-Parameter Logistic Method.
- You have potency results from several independent assay runs and want one combined estimate: use Bioassay — Combine Assays.
Data you need
Use one row per measurement. The first (grey) row holds the column names.
- A numeric column with the response, for example weight gain or absorbance.
- A numeric column with the dose. Zero (blank) doses are allowed. Negative doses are not.
- A column that names the preparation of each row, for example Standard and TestA. The text for the standard must be the same in every row.
- Optionally, a column that identifies a block, plate or run.
Include the standard and at least one test preparation. Use at least 3 non-zero dose levels per preparation where possible, so that linearity can be tested. Replicates at each dose and preparation are needed to estimate the error and to check the model.
Weight Gain (g) | Dose (mg) | Preparation |
|---|---|---|
5.07 | 0 | Standard |
5.61 | 0 | Standard |
14.44 | 5 | Standard |
4.58 | 0 | TestA |
… | … | … |
How to run Bioassay — Slope Ratio Method in Zometric Statistical Software
Sign in to Zometric Statistical Software. You can run Bioassay — Slope Ratio Method in the Statistical Workspace, where most people work, or on its own tool page.
In the Statistical Workspace
- Open Statistical Workspace.
- In the Data grid, type the column names in the first (grey) row, then type or paste (Ctrl+V) your data below. Put the response, the dose and the preparation name in three columns, with one row per measurement.
- Click + Add Tool, search for Bioassay — Slope Ratio Method and open it. It is listed under Bioassay. You can also find it under Browse › Regression.
- In Options: Bioassay — Slope Ratio Method, choose your columns and settings (see Options below).
- Click Calculate. The results appear above the data.
- To keep them, use Download › (PDF, Word or Excel), or Export › to put several analyses into one file.
Only columns with a value in the first data row are sent to the tool, so don't leave the first cell of a column blank.
On the tool page
- Open Statistical Tools and click Bioassay — Slope Ratio Method (category: Bioassay).
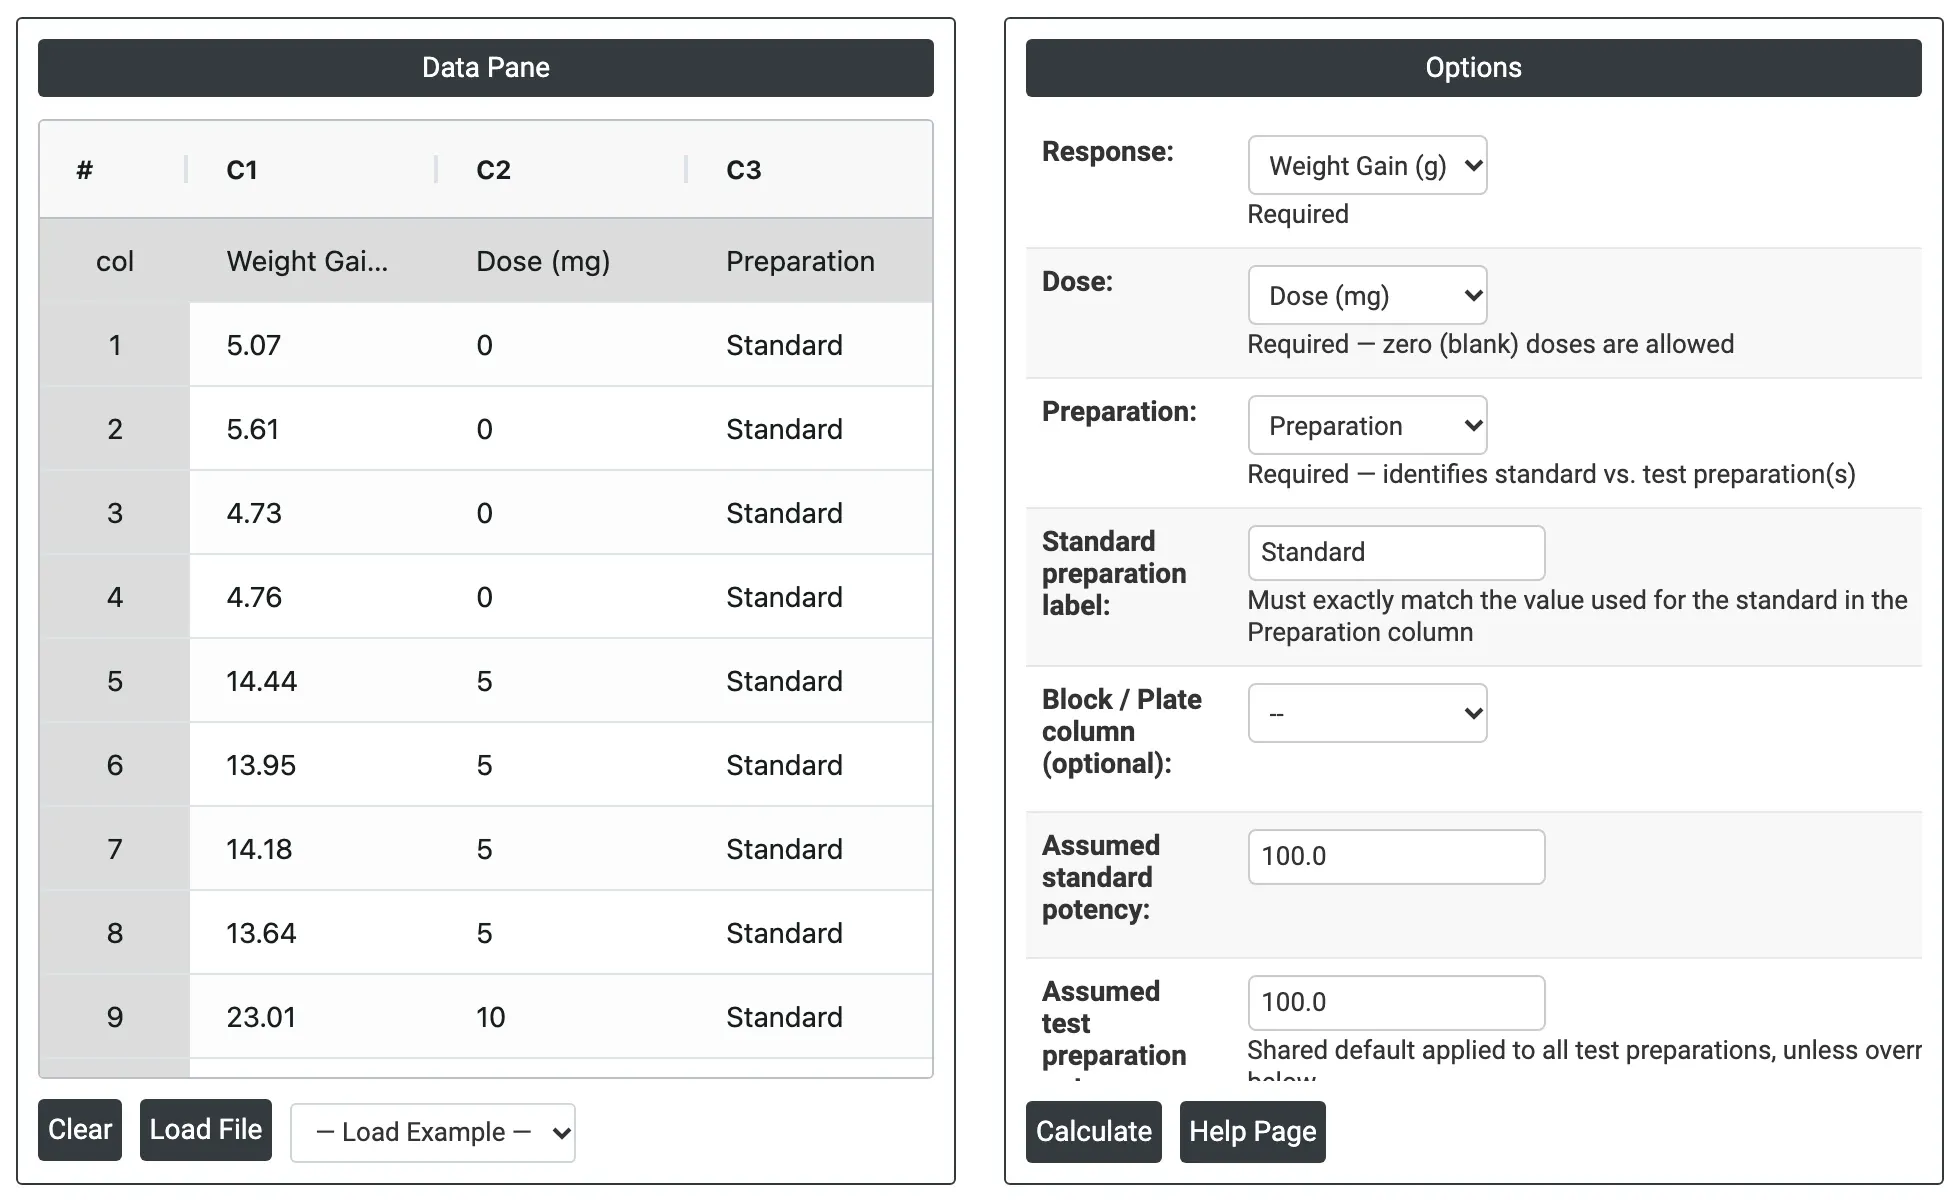
- Enter data in the Data Pane the same way, use Load File to open an Excel or CSV file, or pick a dataset from — Load Example —, which also fills in the options. The example is listed as vitamin-assay.
- Set the Options and click Calculate.
- Use Download › to save the results as PDF, Word or Excel.
No account yet? Talk to us for a demo or a trial.
Options
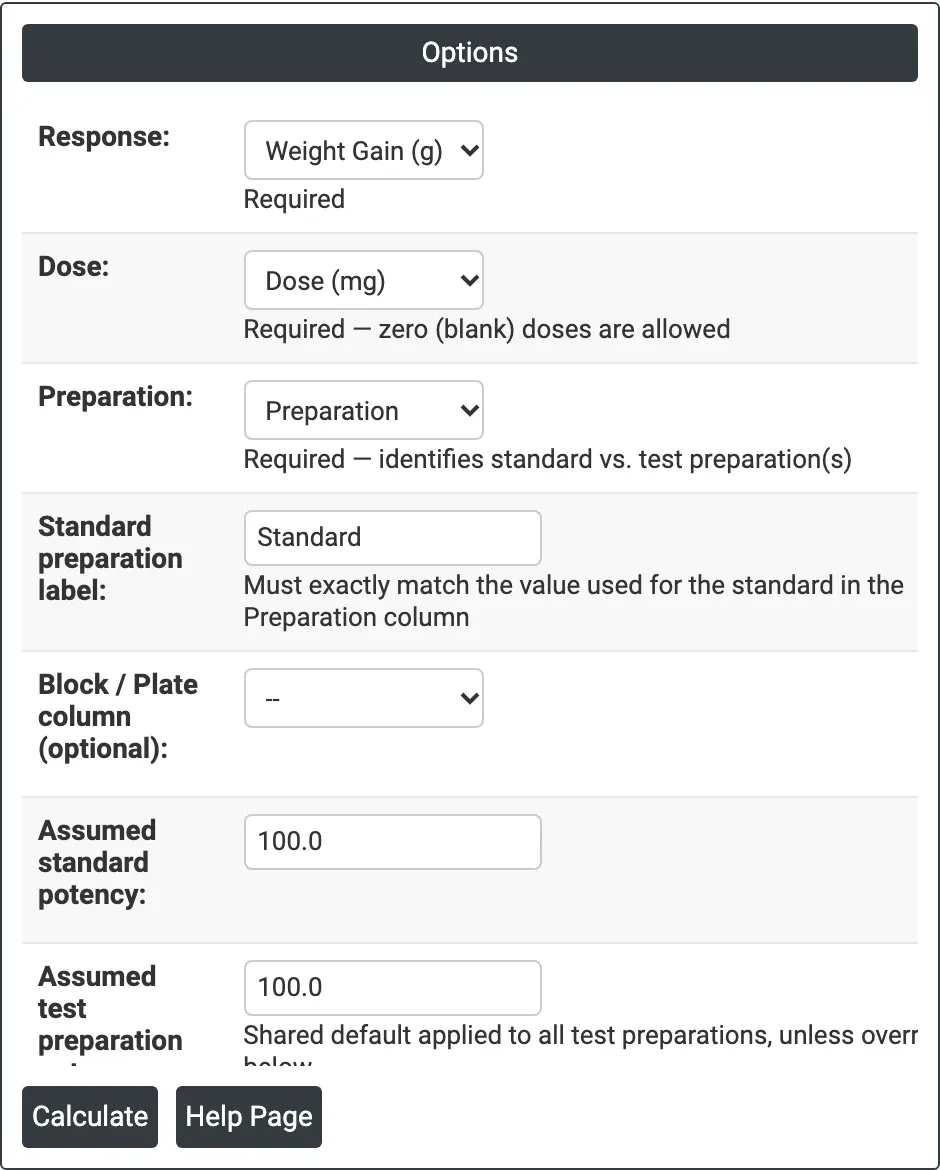
The tool page and the Workspace show the same 27 options, in this order.
Columns and labels
- Response: the column with the measured response, for example weight gain or absorbance. Required.
- Dose: the column with the dose. Required. Zero (blank) doses are allowed.
- Preparation: the column that says which preparation each row belongs to, standard or test. Required.
- Standard preparation label: the exact text used for the standard in the Preparation column. Required. Default Standard. It must match exactly.
- Block / Plate column (optional): a column that identifies a block, plate or run, if the assay has one. Default: none.
Potency
- Assumed standard potency: the nominal (labeled) potency of the standard. Default 100.
- Assumed test preparation potency: the nominal potency shared by all test preparations, unless you override it below. Default 100. The tool uses the assumed potencies to put the estimated potency on the scale of the labeled potencies.
- Per-preparation potency overrides (optional): nominal potencies for particular test preparations, written as
TestA=110, TestB=95. They replace the shared default for those preparations. - Dilution factor: multiplies the final estimated potency and its confidence limits. Use it when the test material was diluted before the assay, relative to the dose scale you entered. Default 1.
Confidence and compliance
- Confidence level (%): the level for the potency confidence interval. Default 95. Allowed values are 50 to 99.999.
- Compliance lower limit (%): the lowest acceptable relative potency. Default 75.
- Compliance upper limit (%): the highest acceptable relative potency. Default 125. The lower limit must be less than the upper limit.
- Potency CI error term: the variance used for the confidence limits. Regression residual (default) uses the residual of the fitted common-intercept model. Pure error uses only the replicate variance within each dose and preparation, which is the pharmacopoeial default. Pure error needs replicates: if no dose of any preparation has more than one reading, the tool shows an error and does not calculate. See Regression residual or pure error under Output.
- Significance level for validity tests (α): the threshold for the regression, intercept and linearity tests. Default 0.05. Allowed values are 0.001 to 0.5.
Assumption checks
- Normality test: Shapiro-Wilk (default), Cramér-von Mises or Anderson-Darling. It is run on each dose-preparation group.
- Homogeneity of variance test: Levene (default), Bartlett, Cochran's C or Hartley's Fmax.
- Outlier test: Standardized residual threshold (default), Grubbs' test, Generalized ESD or Dixon's Q (n = 3-30 per group only).
- Outlier threshold (standardized residual method): the absolute standardized residual above which a case is flagged. Default 2. It is used only when Outlier test is Standardized residual threshold.
Extra analyses
- Include quadratic regression term: unticked by default. Tests whether a common curvature term explains part of the non-linearity.
- Show non-linearity broken out per preparation: unticked by default. Splits the non-linearity into one part for each preparation.
Output sections
- Show case diagnostics table: ticked by default. Lists each observation with its fitted value, residual and outlier flag.
- Show normality / homogeneity of variance tests: ticked by default.
- Show dose-response graph: ticked by default.
- Show box plot by dose-preparation group: unticked by default.
- Show dot plot by dose-preparation group: unticked by default.
- Show bar plot by dose-preparation group: unticked by default.
- Show normal probability plot of residuals: unticked by default.
Output
The results appear in this order.
- Summary Statistics: for each preparation and dose, the number of observations (N), the Mean and the SD.
- Separate Regression (per Preparation): a straight line fitted to each preparation alone, with its intercept, slope, equation, SE(Slope) and R-Sq. Use it to see how well each preparation follows a line.
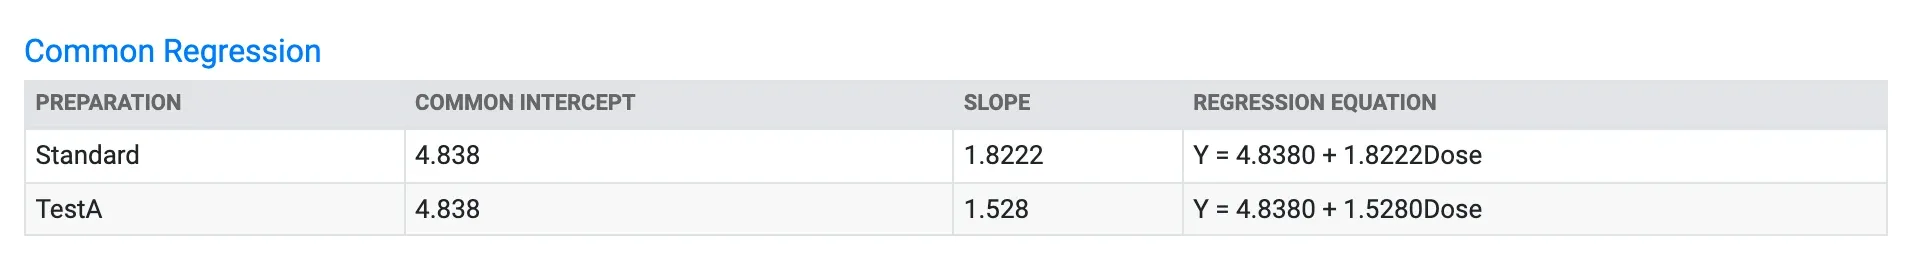
- Common Regression: the lines refitted with one Common Intercept. The slopes in this table are the ones used for the potency.
- Validity of Assay — Analysis of Variance: the ANOVA table with Regression, Preparations (Slope Differences), Intercept, Non-linearity, Residual and Total, with DF, SS, MS, F-Value and P-Value.
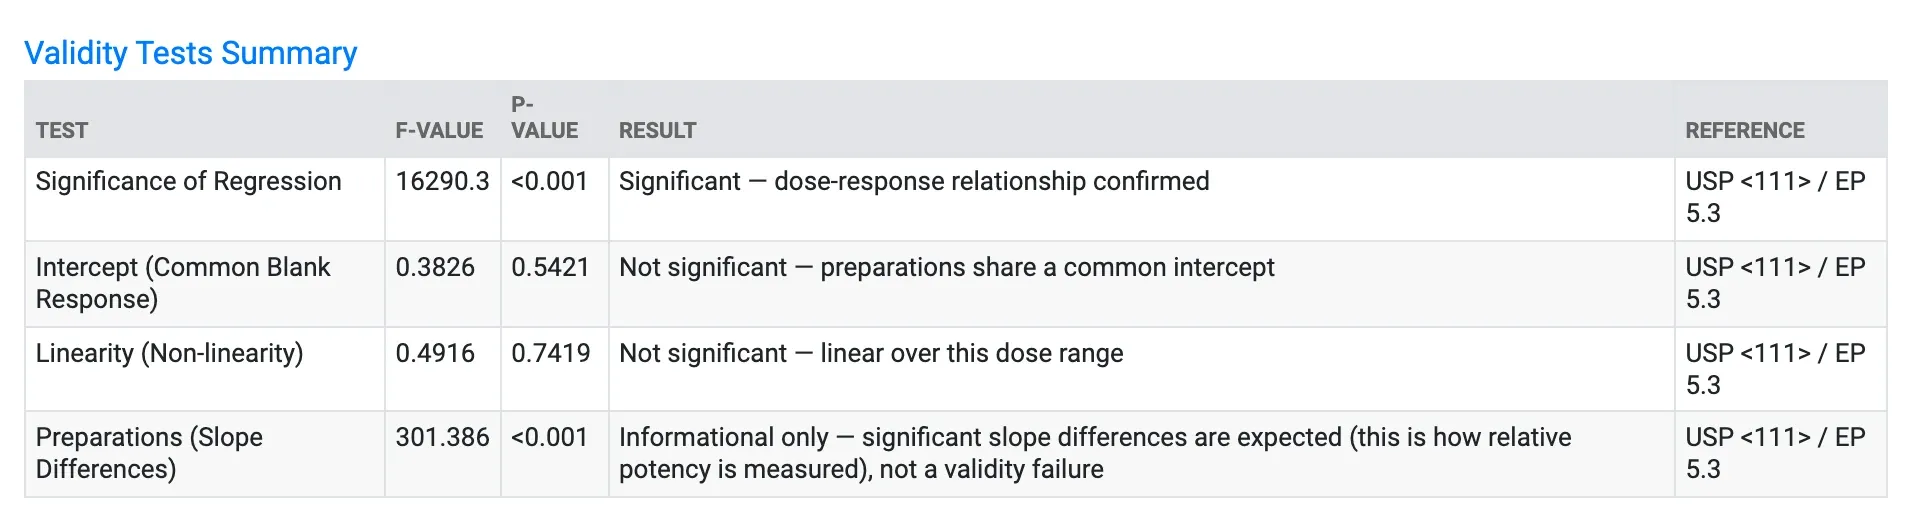
- Validity Tests Summary: one line for each test with a plain-language result. A significant regression is good. A non-significant intercept and a non-significant non-linearity are good. Slope differences are informational only.
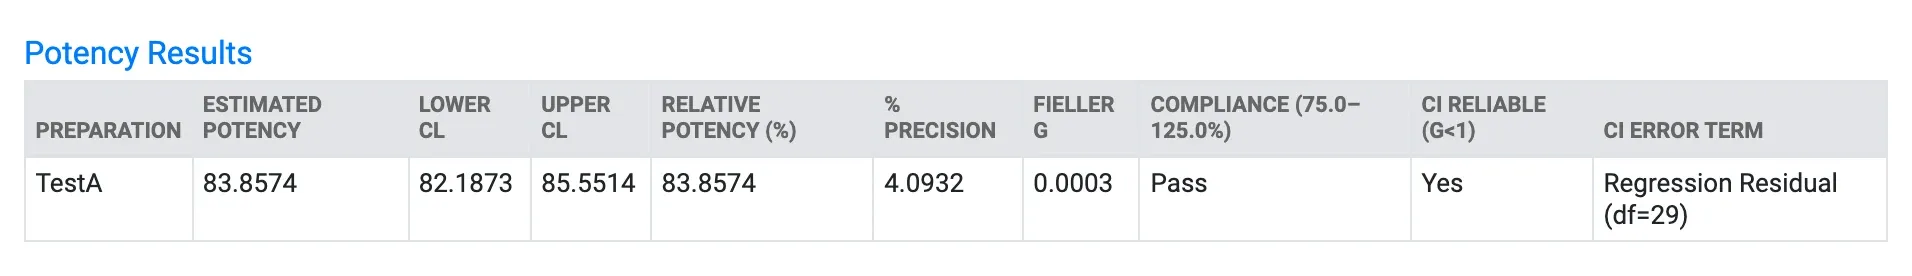
- Potency Results: for each test preparation the Estimated Potency, Lower CL, Upper CL, Relative Potency (%), % Precision (the width of the confidence interval as a percentage of the lower limit), Fieller g, Compliance (Pass or Fail against your limits), CI Reliable (G<1) and the CI Error Term used.
- Normality Test (per group) and Homogeneity of Variance Test, unless you switched them off.
- Case diagnostics, if ticked, with the cases flagged as outliers.
- Dose-Response Plot, with the observed points and the fitted line for each preparation. The lines start at the common intercept. Any other plot you ticked follows.
Read the results from the top. Check the three validity tests first. If the intercept or the linearity test is significant, the slope ratio model does not describe the data well, and the potency should not be reported as it stands. A narrow confidence interval and Fieller g well below 1 mean the potency is well determined. Compliance checks only that the estimated potency lies between your two limits. It does not look at the confidence limits.
Regression residual or pure error. Both choices of Potency CI error term feed the same Fieller calculation. Only the variance and its degrees of freedom differ:
- Regression residual: MS = SS(residual after the common-intercept fit) / its DF. It holds the replicate scatter plus any small departure from a common intercept and any small non-linearity.
- Pure error: MS = SS(pure error) / its DF, where SS(pure error) is the sum of the squared deviations of each reading from the mean of its own dose and preparation. It holds the replicate scatter only.
The choice changes Lower CL, Upper CL, % Precision, Fieller g and the CI Error Term column. The estimated potency, the separate and common regression tables, the ANOVA table and the validity tests stay the same, because the F-tests always use the Residual row of the ANOVA table as their denominator. For a valid assay the two intervals are close. Choose Pure error when your procedure, or the earlier results you compare with, use that convention.
Worked example
This example uses the tool's own example dataset, listed as vitamin-assay in — Load Example —. On the tool page, pick it and click Calculate. The example fills in Response = Weight Gain (g), Dose = Dose (mg), Preparation = Preparation and Standard preparation label = Standard. Show case diagnostics table is unticked in the example, to keep the report short. All other options keep their defaults.
A nutrition lab compares a new vitamin supplement (TestA) with a Standard in a rat growth assay. Both are given at 0, 5, 10 and 20 mg, to four rats each, so there are 32 rats. The response is the weight gain in grams.
Summary and regressions.
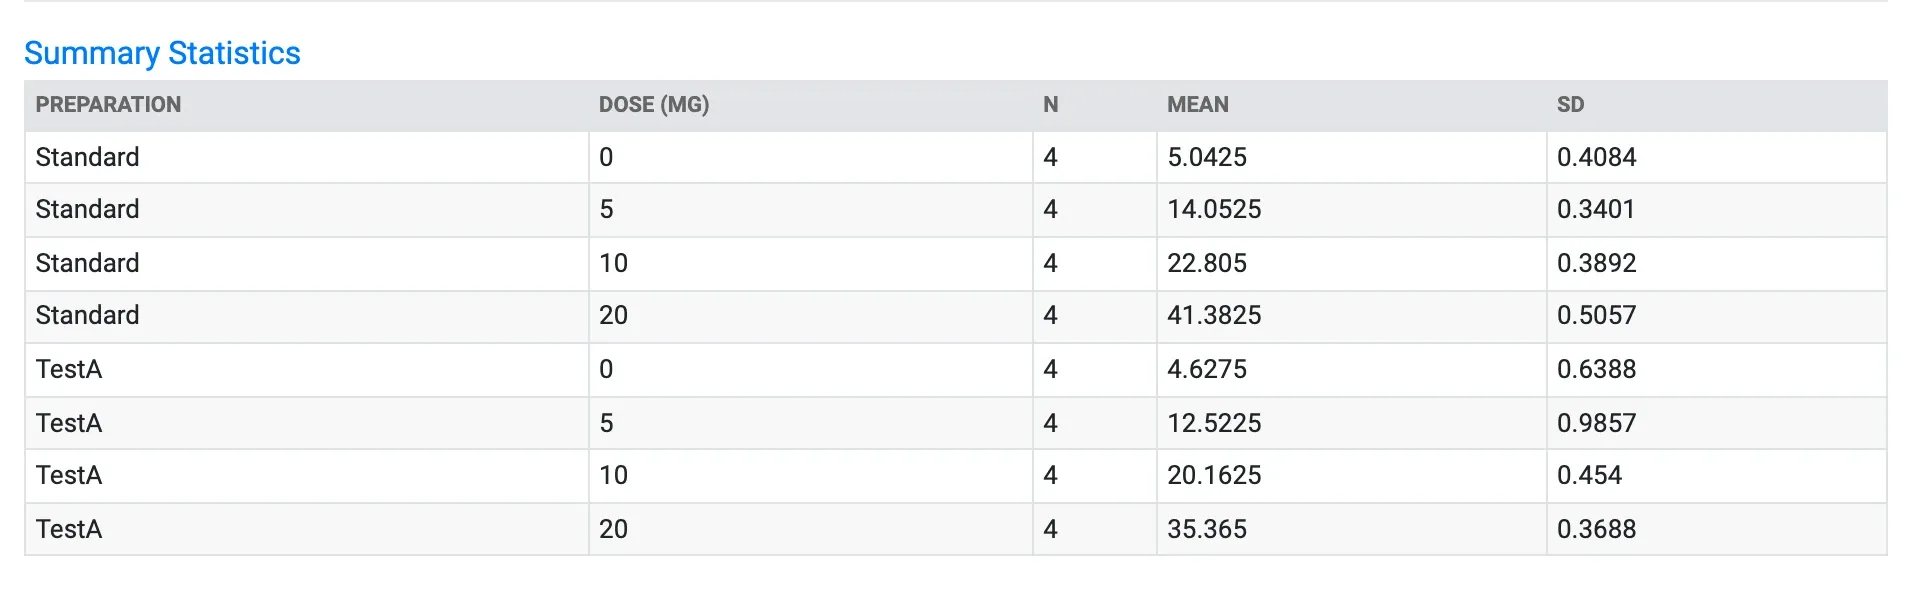
Preparation | Dose (mg) | N | Mean | SD |
|---|---|---|---|---|
Standard | 0 | 4 | 5.0425 | 0.4084 |
Standard | 5 | 4 | 14.0525 | 0.3401 |
Standard | 10 | 4 | 22.805 | 0.3892 |
Standard | 20 | 4 | 41.3825 | 0.5057 |
TestA | 0 | 4 | 4.6275 | 0.6388 |
TestA | 5 | 4 | 12.5225 | 0.9857 |
TestA | 10 | 4 | 20.1625 | 0.454 |
TestA | 20 | 4 | 35.365 | 0.3688 |
Preparation | Common Intercept | Slope | Regression Equation |
|---|---|---|---|
Standard | 4.838 | 1.8222 | Y = 4.8380 + 1.8222Dose |
TestA | 4.838 | 1.528 | Y = 4.8380 + 1.5280Dose |
With one common intercept of 4.838 g, the Standard gains 1.8222 g per mg and TestA gains 1.528 g per mg. The separate lines are very close to this: slopes of 1.816 and 1.5342, and R-Sq of 0.9991 and 0.9974.
Validity.
Test | F-Value | P-Value | Result | Reference |
|---|---|---|---|---|
Significance of Regression | 16290.3 | <0.001 | Significant — dose-response relationship confirmed | USP <111> / EP 5.3 |
Intercept (Common Blank Response) | 0.3826 | 0.5421 | Not significant — preparations share a common intercept | USP <111> / EP 5.3 |
Linearity (Non-linearity) | 0.4916 | 0.7419 | Not significant — linear over this dose range | USP <111> / EP 5.3 |
Preparations (Slope Differences) | 301.386 | <0.001 | Informational only — significant slope differences are expected (this is how relative potency is measured), not a validity failure | USP <111> / EP 5.3 |
The regression is significant (F = 16290.3, P < 0.001). The intercept test is not significant (P = 0.5421), so the two preparations share a blank response. The non-linearity test is not significant either (P = 0.7419), so the response is linear over 0 to 20 mg. The slope difference is highly significant (F = 301.386, P < 0.001). That is expected and shows TestA is less potent. The model is valid.
Potency.
Preparation | Estimated Potency | Lower CL | Upper CL | Relative Potency (%) | % Precision | Fieller G | Compliance (75.0–125.0%) | CI Reliable (G<1) | CI Error Term |
|---|---|---|---|---|---|---|---|---|---|
TestA | 83.8574 | 82.1873 | 85.5514 | 83.8574 | 4.0932 | 0.0003 | Pass | Yes | Regression Residual (df=29) |
The relative potency of TestA is 1.528 / 1.8222 = 83.86%, with 95% confidence limits 82.19% to 85.55%. Fieller g is 0.0003, far below 1, so the interval is reliable. It is based on the regression residual with 29 degrees of freedom (32 observations minus 3 fitted parameters). The result is Pass against the limits of 75% to 125%, but TestA is clearly weaker than the Standard.
Assumption checks.
Test | Statistic | P-Value | Result |
|---|---|---|---|
Levene | 0.4859 | 0.8353 | Equal variances |
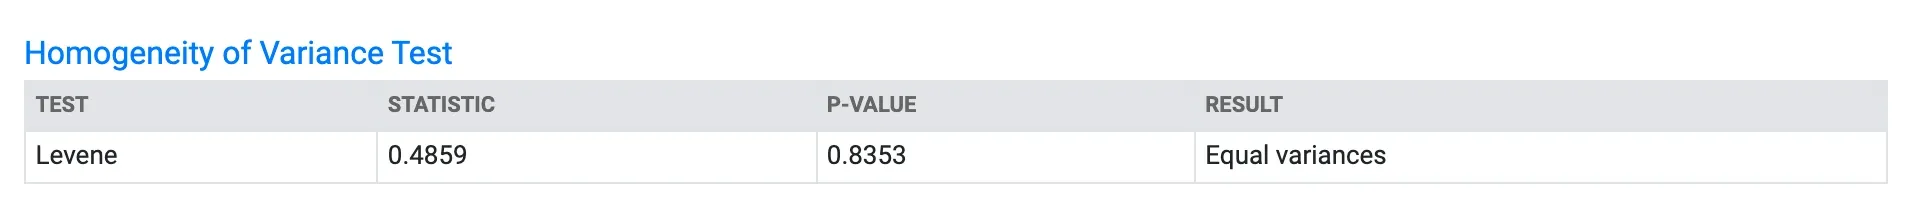
All eight groups pass the Shapiro-Wilk test (smallest P 0.146 for Standard at 20 mg). Levene's test gives P = 0.8353, so the variances are equal.
Dose-response plot.
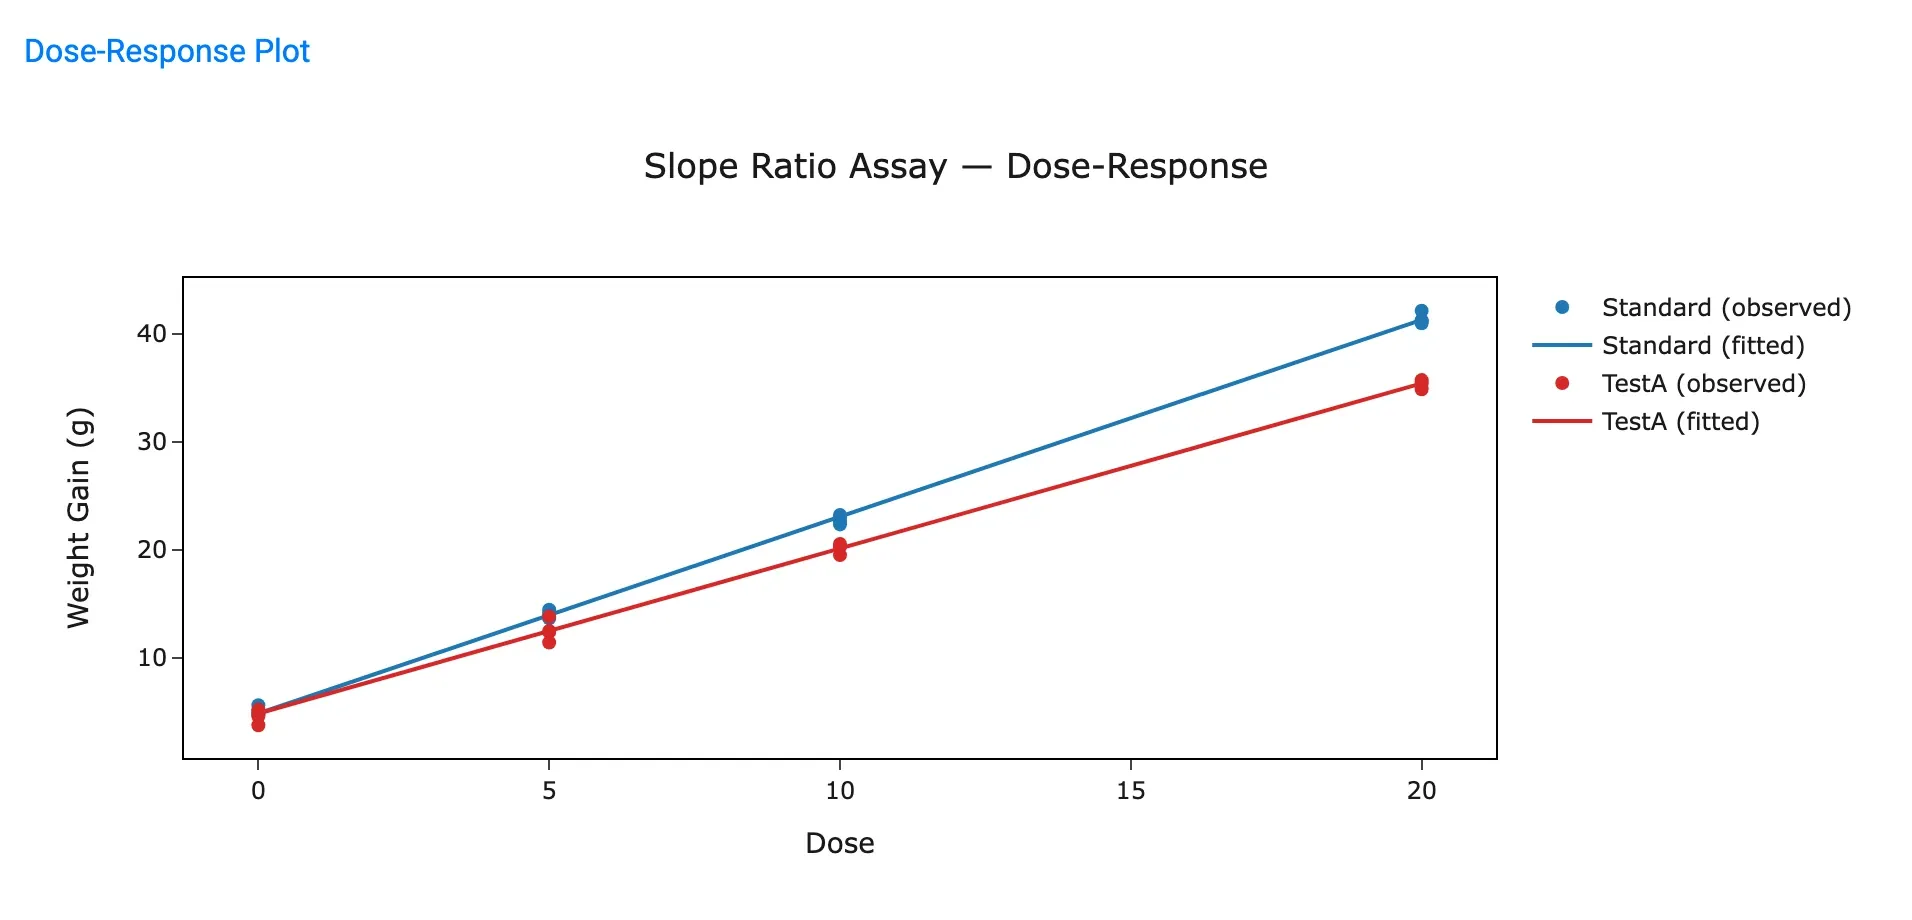
The two lines start at the same point and fan out. The flatter TestA line is the lower potency.
Try this.
- Tick Show case diagnostics table. In the app, the standardized-residual rule flags three TestA rats, at doses 0 and 5, with standardized residuals between 2.1 and 2.6.
- Then set Outlier test to Grubbs' test. None of the eight groups has an outlier by that test, so the flagged rats need not be removed.
- Set Potency CI error term to Pure error. This uses only the replicate variance, with 24 degrees of freedom here (32 observations minus 8 groups), the same as the Residual row of the ANOVA table. The potency stays 83.8574%, and the 95% limits become 82.09% to 85.6516%, slightly wider than with the regression residual.
Frequently asked questions
What is a slope ratio assay?
It estimates the relative potency of a test preparation against a standard by comparing straight dose-response lines on the dose scale, not log dose. All preparations share a common intercept, the response at zero dose, and each has its own slope. The relative potency is the test slope divided by the standard slope.
When should I use the slope ratio method instead of the parallel line method?
Use the slope ratio method when the response increases linearly with the dose itself, typically in assays with a zero-dose blank. Use the parallel line method when the response is linear in log dose. For counts of responding subjects, use the quantal response method.
Which validity tests must pass?
Three checks: a significant regression, a common intercept (the preparations agree on the blank response) and linearity over the tested dose range. Significant slope differences between preparations are expected and are not a validity failure.
What doses and replicates do I need?
Use at least 3 non-zero dose levels per preparation where possible, so that linearity can be tested. Doses may be zero but not negative. A shared zero-dose treatment helps estimate the common intercept. Use enough replicates at each dose and preparation to estimate the error well.
What does Fieller g mean?
Fieller g measures how well the slope of the standard is determined. When g is below 1, the confidence interval for the potency is reliable. A g close to 1 or above means the standard slope is too uncertain and the interval cannot be trusted.
What does the compliance result check?
It checks whether the estimated relative potency lies between Compliance lower limit (%) and Compliance upper limit (%). It does not test the confidence limits. Look at the Lower CL and Upper CL too if your specification applies to them.